Experiment
The previous experiments outlined some of the choices that must be made before comparing texts using a Doc2Vec model and a measure such as cosine similarity, e.g. which parameters to set when training the underlying model: vector size, window (no. of tokens to the left and right of the node/current token) and minimum word count. In this experiment, we will test changing some of these parameters and report the outcome.
Experiments 1 and 2
In experiments 1 and 2 we ended up using these parameter settings when training the model: vector_size=100, window=5, min_count=5, workers=4, epochs=30. In addition, we had a chunk size of 100 words which was fed to Doc2Vec, whether we used lemmas or semantic tags as input.
Chunk size
To see to what extent chunk size matters, I tested three different ones: 100 and 1,000 tokens and s-units (sentences as recognised by the tokenizer). With our now default cosine similarity threshold of >= 0.7, the difference between chunk sizes of 100 and 1,000 words was only two texts when comparing lemmas. Using s-units, however, lowered the number of outputted text pairs from 62 (100 lemma chunks) / 64 (1,000 lemma chunks) to 55. This seems to show that using s-units, i.e., much smaller chunk sizes of lemmas, affects the model performance quite a lot.
Next, I changed the vector size from 100 to 200. This resulted in only a handful of text pairs reaching our threshold. According to Copilot, having a corpus of >150 million words (tokens) gives us a rich vocabulary and using vector sizes in the 300 - 500 area would seem reasonable, even though the rather limited number of texts < 1,700 is quite low. The next table summarises the recommendations Copilot gave.
| Vector size | Pros | Cons |
|---|---|---|
| Small (e.g., 50-100) | Fast training, baseline models | May miss subtle semantic details |
| Medium (e.g., 200-300) | Balanced performance | Good for most NLP tasks |
| Large (e.g., 500+) | Rich representation | Risk of overfitting, slow training |
Based on the recommendations and the above result when using a vector size of 200 (I also tried 150), I increased the vector size to 300. This resulted in very few text pairs reaching a cosine similarity >= 0.7. In fact, I had to reduce the threshold to >= 0.55 to get more than 20 pairs. What is more, now chunk size did not seem to influence the outcome that much: s-unit: 20 pairs, 100 lemmas : 19 pairs and 1,000 lemmas: 23 pairs. Next, I will experiment with different min_counts and window (size).
Window (size) and min_count (frequency)
Changing the window (size) from 5 to 10 did not significantly change the outcome of the comparison. In fact, we got fewer pairs that reached the threshold of >= 0.55 compared to the window (size) of 5 tokens.
Reducing min_count from 5 to 2 yielded a few more pairs above the >= 0.55 threshold and this time it was chunk size = 100 that outputted most pairs, namely 29 (chunk size 1,000 = 27 and chunk size s-unit = 25).
Using semantic tags and not lemmas as input did you yield very different results, so I am sticking with lemmas for the time being. In a future experiment, I might see if including the more fine-grained semantic tags will impact the output significantly.
The same goes for using parts of speech as input to the model, i.e. there is no immediate difference in the number of pairs that reach the => 0.55 threshold. If nothing else, this confirms the robustness of the model in pointing to pairs that exhibit likeness on the token level, whether the tokens are lemmas, parts of speech or sematic tags.
As a final "tinkering", I changed all lemmas tagged as proper nouns to the tag: 'propn', to avoid spurious differences due to place and personal names in the texts.
With the parameter settings vector_size=300, window=5, min_count=2, workers=4, epochs=30 I got the following list of text pairs with a cosine similarity >= 0.55 (based on lemmas). Note the overlap in genre, i.e. nearly all pairs above the threshold have the same genre label.
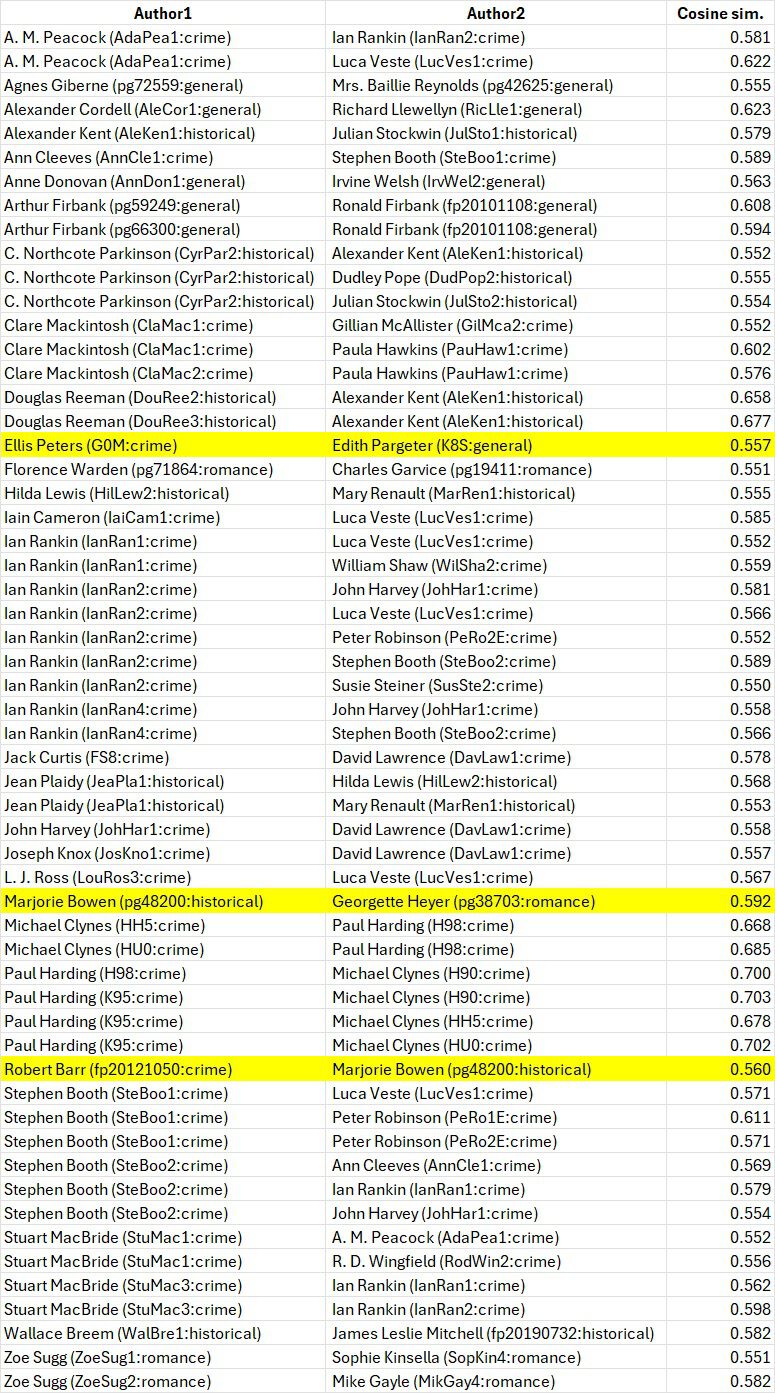
Figure 1. Cosine similarity >= 0.55 of 1,685 fiction texts in the CBF
In follow-ups to these preliminary experimentations, we will build on what we have learned, formulate some research questions/hypotheses and report on the findings.